AI Agents Turn Legacy Data Modernization Into a Trust Preservation Problem
Anudeep Reddy Puthalapattu, Senior AI Data Engineer at HCL America, explains why financial institutions need governance, lineage, and business context embedded in the data platform as AI becomes a new consumer of enterprise data.
Make AI Data Press one of your go-to sources on Google


In my experience, modernization isn't just a data movement problem, but also a trust preservation problem.
Anudeep Reddy Puthalapattu
Financial institutions can now migrate decades of legacy data into modern cloud platforms, but often face challenges preserving the context around it. A pipeline can make it through migration intact while the business rules, ownership, reporting dependencies, and controls that made its output trustworthy get lost along the way. As AI agents begin querying enterprise data more directly, those gaps become more consequential.
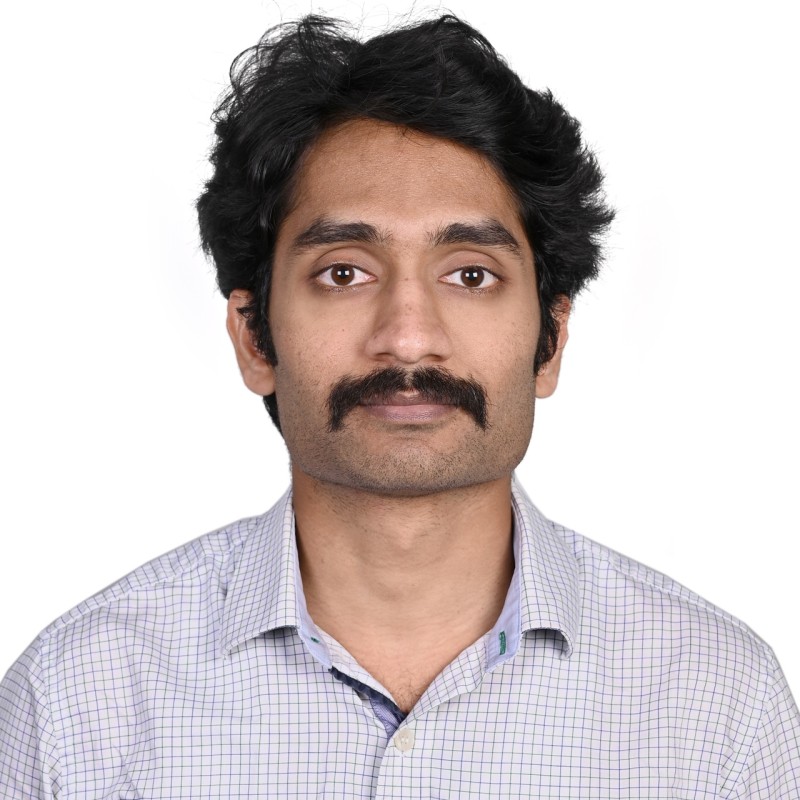
Anudeep Reddy Puthalapattu is a Senior AI Data Engineer at HCL America, working on data modernization in the financial services industry. He’s led the migration of more than 120 legacy pipelines from Hadoop, SQL Server, and SAS into Snowflake and designed a governance layer covering more than 500 Snowflake tables. That combination of migration work and governance design has given him a close view of what has to survive a modernization effort once the underlying technology changes.
"In my experience, modernization isn't just a data movement problem, but also a trust preservation problem," Anudeep says. Legacy platforms often carry years of reconciliations, exceptions, reporting dependencies, and undocumented workarounds. Replacing them means preserving business meaning that may be scattered across code, processes, and institutional knowledge.
Why lineage has to move with the workload
Lineage has to move with the workload because the relationships around the data often matter as much as the data being transferred. "I treat lineage as a migration deliverable, not just documentation to add later at the end," Anudeep says. Before changing a pipeline, he maps where the data comes from, which rules and transformations shape it, what depends on it downstream, and where the output is used. That process often uncovers hidden dependencies that can turn a routine migration into a much riskier project.
The largest gaps tend to appear where one part of the system hands data to another. During extraction, source definitions, code mappings, timestamps, or ownership can disappear. Transformation creates another failure point because years of business rules and exceptions may be embedded in legacy SQL, ETL jobs, or operational processes without ever becoming formal documentation. Even after the tables and pipelines move successfully, teams can still lose sight of which reports, downstream data sets, or business processes rely on them.
“I also connect lineage to validation so teams can trace a reported figure back through the transformations and understand what changed between the legacy and modern versions,” Anudeep explains. Source-to-target mappings, pipeline definitions, transformation documentation, operational logs, and reconciliation create the record needed to do that. For higher-risk workloads, he also uses parallel validation to confirm that the new pipeline preserves the intended business meaning.
Context as a requirement for usable data
Lineage explains how data moved through the system, but that history still needs business context before downstream users can make reliable decisions. A modern platform can provide processing power, scalability, and security while still leaving basic questions unanswered about what a field represents, how it was calculated, who owns it, or which policies govern its use. "Technical lineage tells me where a column came from, but business metadata tells me what value it actually represents, how it was derived, what policy or control applies to it, who's accountable for it, and whether it's appropriate for a particular use case," Anudeep says. "Availability isn't the same as usability."
The metadata needed to close that gap falls into several connected categories. Business meaning covers definitions, calculation logic, approved use cases, data classification, and accountable ownership. Provenance and transformation context capture source lineage, transformations, timestamps, freshness, and relevant job or release versions. Control metadata adds the restrictions around the data, including masking requirements, retention expectations, quality rules, reconciliation status, and audit evidence.
Together, those layers show downstream systems not only what data exists, but whether it can be trusted, is current, and is appropriate for the decision at hand, a distinction that becomes even more important as AI agents increasingly consume the data directly.
AI raises the stakes of incomplete context
An agent can form a natural-language query against enterprise data without carrying the institutional knowledge employees have accumulated around the underlying systems. If a financial institution moves years of transaction data into a cloud warehouse while leaving its metadata incomplete, the agent may be technically capable of reaching information that lacks the context needed to use it appropriately.
Anudeep's answer is to attach governance to the data through enforceable metadata and platform controls. Sensitive and business-critical data needs classification and accountable ownership, while definitions, lineage, quality, freshness, retention, and approved-use information need to travel with it. Agents can then operate against curated, approved sources with enough provenance to explain where their outputs came from. "The key point is that AI should consume the governed data layer, not become the layer that decides what's governed," he says. That way, an agent can help users retrieve, summarize, or analyze information within established boundaries without taking on decisions about whether a field is sensitive, a source is appropriate, or a user should have access.
Governance becomes part of the control layer
Policy enforcement needs to happen close to the data, where it can be applied consistently across every application that consumes it. “It should live in the data platform’s policy and control layer, close to the data and separate from the AI application,” Anudeep says.
Within that layer, multiple enforcement mechanisms work together. Identity and role-based access, sensitive data classification, retention rules, masking policies, approved data products, and audit logging provide the foundation. Row- and column-level policies can further limit what an agent is able to retrieve, while higher-risk actions such as exporting or combining sensitive data can require purpose-based restrictions or human approval. “The controls need to be deterministic, testable, and auditable."
The architectural distinction matters because the model and the control system serve different purposes. "Models are probabilistic, but security and compliance controls cannot be," Anudeep says. "Put enforcement in the control plane and let AI consume governed data within those established limits." Auditability also needs to extend to each interaction. “You need to be able to see what identity made the request, what data was accessed, what policy was applied, and what context informed the response,” he explains. That way, teams have a clear record of how governance was enforced from the initial request through the resulting action.
Reusable templates and automated workflows for scaled governance
Embedding more controls into the platform creates another problem if those controls slow delivery enough that teams start looking for ways around them. “The practical answer is to turn governance decisions into platform standards rather than making them a sequence of manual approvals,” Anudeep says.
Role-based access, lineage capture, quality checks, reconciliation, and deployment controls can be built into reusable templates and automated workflows. Central governance teams define the guardrails, while delivery teams work within them through self-service patterns instead of rebuilding the same controls for every project. Exceptions can still be made, but they should have clear ownership, a documented rationale, and an auditable path. That model changes governance from an additional step into part of the normal engineering experience. "Good governance defines a paved road. It shouldn't require every team to rebuild the road."
Continuous auditing combined with continuous judgment
Even a well-designed control layer can drift away from reality as schemas change, new dependencies emerge, and teams deploy pipelines outside the expected path. Metadata therefore needs continuous challenge rather than being treated as accurate simply because it exists.
Automation and AI can help detect those signals at scale. A schema change, a previously unknown dependency, an unusual deployment, or a mismatch between documented and observed data flows can trigger review before the discrepancy survives until the next audit or migration. That gives governance teams a continuously maintained record to validate instead of relying on periodic reviews to rediscover the state of the system.
Human accountability remains central to that model. Business owners need to validate meaning, approve important exceptions, and review higher-risk changes because automated metadata can still be incomplete or wrong. “Automate detection and evidence gathering while keeping the people accountable for interpretation and critical decisions,” Anudeep says.
AI introduces a new data consumer, but the governance model remains
Financial institutions already have governance practices built around the people, applications, and reports that use their data. As agents become another interface into the same platforms, those controls need to extend to a new kind of consumer without becoming dependent on the agent itself. That means carrying business meaning, permissions, lineage, and evidence with the data from the beginning, then continuously validating that context as systems and dependencies change.
"The key principle is that an agent should be treated as a new type of data consumer, not as an exception to the governance model," Anudeep says. The interface may be changing, but the underlying requirement remains the same: organizations need to know who or what is accessing their data, what that consumer is allowed to do with it, and whether the information behind the resulting decision can still be trusted.